脑卒中CT数据集
该数据集是脑卒中CT数据集的精炼与预处理版本,面向深度学习语义分割任务(如U-Net)优化,用于从头部CT扫描中自动提取出血与缺血等病理区域,辅助快速临床诊断
基本信息
资源简介
脑卒中CT数据集
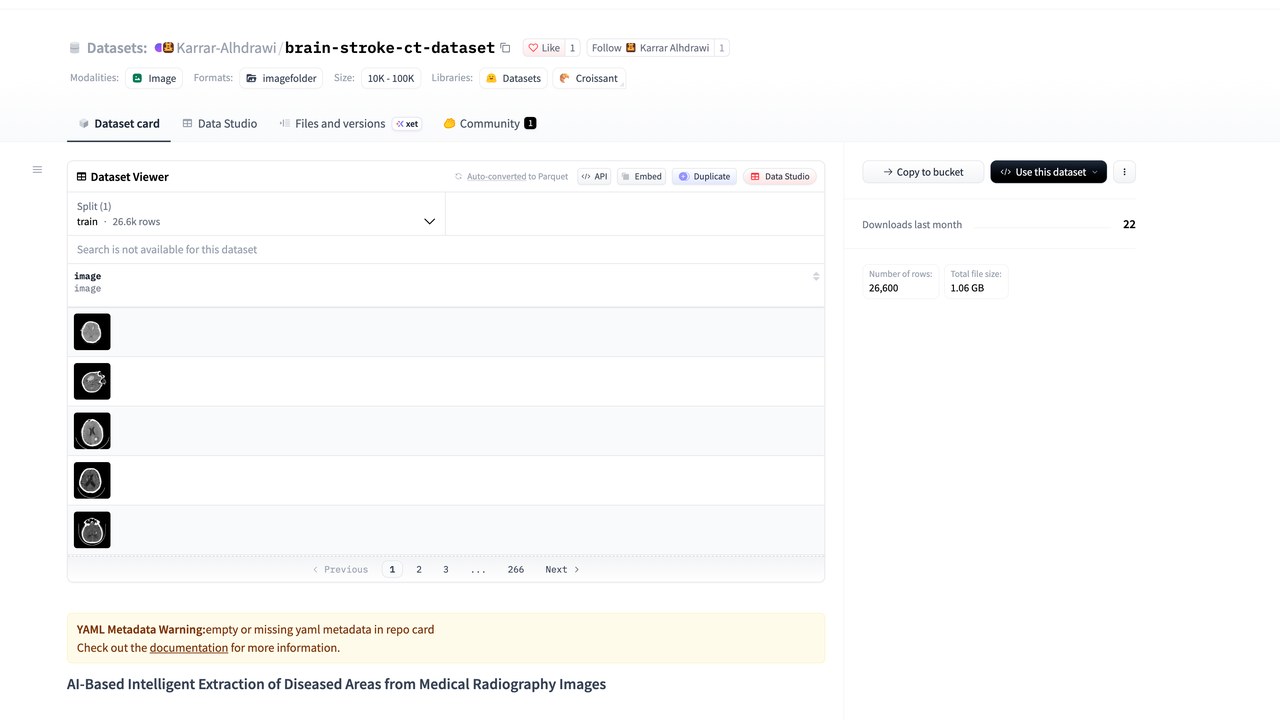
Karrar-Alhdrawi/brain-stroke-ct-dataset
该数据集是脑卒中CT数据集的精炼与预处理版本,面向深度学习语义分割任务(如U-Net)优化,用于从头部CT扫描中自动提取出血与缺血等病理区域,辅助快速临床诊断。原始数据来自Kaggle脑卒中CT数据集,由放射科医师制作并获土耳其卫生研究院(TUSEB)支持。数据集共990个文件,按Bleeding等目录组织图像,适用于医学影像分割模型的训练与评估(来源 Hugging Face)。
【数据集背景】
源站首次发布:2026-05-04。
【数据内容】
源站描述(机器翻译,仅供参考):基于AI的医学放射影像病变区域智能提取 1. 概述 本数据集是脑卒中CT数据集的精炼与预处理版本,专门针对使用U-Net等深度学习架构的语义分割任务进行了优化。本工作属于一个研究项目的一部分,该项目专注于从头部CT扫描中自动提取病理区域(出血和缺血),以辅助快速临床诊断。 2. 来源与归属 原始数据最初来源于Kaggle上的脑卒中CT数据集,该数据集由放射科医师制作,并得到土耳其卫生研究院(TUSEB)的支持。 3. 预处理与方法 原始数据集提供了原始CT图像和“Overlay”图像,专家在其中手动标注了病变区域,使用
【数据结构与技术规格】
文件数 990 个,合计 83.59 MB。
【主题与分类】
本站分类:循环系统疾病。
【获取与许可】
源站页面:https://huggingface.co/datasets/Karrar-Alhdrawi/brain-stroke-ct-dataset
下载信息
注册下载
需要注册 Kaggle 账号并登录后下载,适合需要跟踪下载记录和使用 API 的用户。
暂未开放公开下载
无需注册即可直接获取公开样本或文档,适合快速预览和评估数据集质量。
免登录有偿下载
公开数据集受托下载与技术交付服务。
提供高速下载与技术交付服务(收技术服务费,非数据销售)
暂未开放当前数据集主要来源为 Kaggle 公开托管,完整影像包建议通过原始链接或 Kaggle API 获取。
使用方式
数据集获取与加载(Hugging Face datasets)
# 前置依赖: pip install datasets
from datasets import load_dataset

ds = load_dataset("Karrar-Alhdrawi/brain-stroke-ct-dataset")
print(ds)  # 查看 splits 与字段结构
# 国内网络可先设镜像: import os; os.environ["HF_ENDPOINT"]="https://hf-mirror.com"
git lfs install && git clone https://hf-mirror.com/datasets/Karrar-Alhdrawi/brain-stroke-ct-dataset
数据集大小约 1.60 GB。
仓库文件结构
.gitattributesREADME.mdapp.pybrain-stroke-dataset-v1.zip
数据集卡片摘录(源站说明)
AI-Based Intelligent Extraction of Diseased Areas from Medical Radiography Images
1. Overview
This dataset is a refined and preprocessed version of the Brain Stroke CT Dataset, specifically optimized for semantic segmentation tasks using deep learning architectures like U-Net. This work is part of a research project focused on automating the extraction of pathological regions (Bleeding and Ischemia) from head CT scans to assist in rapid clinical diagnosis.
2. Source & Attribution
The raw data was originally sourced from the Brain Stroke CT Dataset on Kaggle, which was prepared by radiologists and supported by the Turkish Health Institutes (TUSEB).
3. Preprocessing & Methodology
The original dataset provided raw CT images and “Overlay” images where specialists manually highlighted diseased areas using specific colors (Red and Green). To make this data compatible with high-precision segmentation models, a custom Python pipeline was developed to:
- Binary Mask Extraction: Used HSV color masking to isolate the clinicians’ annotations from the overlays, converting them into pure binary masks (White: Diseased, Black: Healthy).
- Normal Case Synthesis: Generated corresponding empty (all-black) masks for healthy brain images to maintain consistency during model training.
- Structural Standardization: Organized the data into a clean
images/andmasks/hierarchy for each category (Normal, Bleeding, Ischemia).
4. Why This Custom Pipeline?
The raw Kaggle dataset is excellent for classification, but lacks ready-to-use binary masks for pixel-wise segmentation. By applying this custom script:
- We standardized the labels for U-Net ingestion.
- We ensured that the model learns the exact morphology of the stroke rather than just its general location.
- We reduced data noise by filtering out non-essential metadata and raw DICOM formats, focusing on standardized PNG outputs.
5. Implementation Script
The following script was used to generate this processed version:
# [
import os
import shutil
import cv2
import numpy as np
from tqdm import tqdm
import kagglehub
from huggingface_hub import HfApi, create_repo

# --- إعدادات الحساب والروابط ---
my_token = "***********"
repo_name = "iraqigold/brain-stroke-ct-dataset"

# مسارات الشغل بداخل الكولاب
raw


## 数据加载示例(图像类)

```python
from PIL import Image
import glob, os

files = (glob.glob(os.path.join(path, "**", "*.png"), recursive=True)
       + glob.glob(os.path.join(path, "**", "*.jpg"), recursive=True)
       + glob.glob(os.path.join(path, "**", "*.tif"), recursive=True))
print("图像文件数:", len(files))
img = Image.open(files[0]); print("尺寸/模式:", img.size, img.mode)

# torchvision Dataset 方式:
# from torchvision import datasets
# ds = datasets.ImageFolder(path)  # 要求 子目录=类别
目录组织与标注格式以源站说明和下载后实际文件为准。
完整数据卡:huggingface.co/datasets/Karrar-Alhdrawi/brain-stroke-ct-dataset
数据缺失?
依托陕西、四川两大基地,我们与超过十家三甲医院建立直接合作关系,覆盖合规授权、采集治理、专业标注、数据交付的全流程,为AI医疗团队提供即拿即用的高质量临床数据。
⚡️ 需要数据支持或标注服务?立即联系我们获取专业方案。