任务导向型静默语音识别文本语料库
面向静默语音识别的任务导向型文本语料库,用于帮助言语障碍患者通过EEG信号进行交流。
基本信息
资源简介
任务导向型静默语音识别文本语料库
【数据集背景】
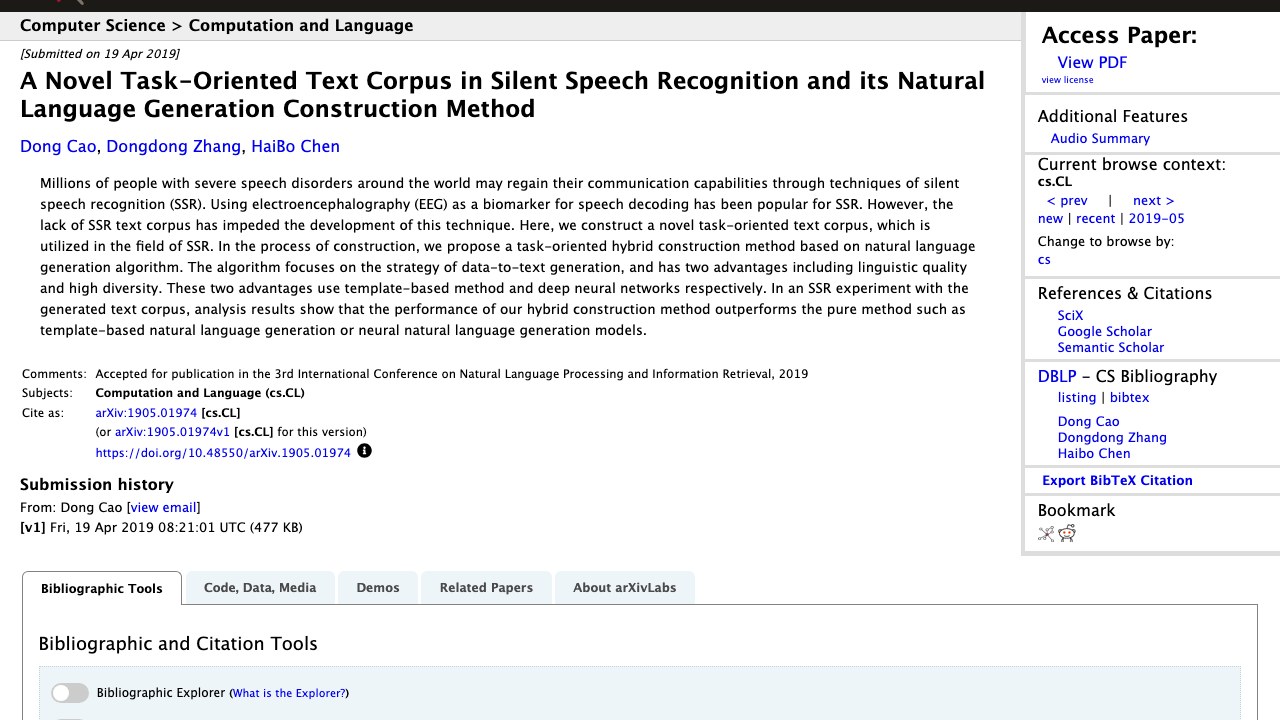
本数据集源站标题为《arXiv Query: search_query=&id_list=1905.01974v1&start=0&max_results=1》。源站首次发布:2019-04-19。
【数据内容】
源站原始描述:Millions of people with severe speech disorders around the world may regain their communication capabilities through techniques of silent speech recognition (SSR). Using electroencephalography (EEG) as a biomarker for speech decoding has been popular for SSR. However, the lack of SSR text corpus has impeded the development of this technique. Here, we construct a novel task-oriented text corpus, which is utilized in the field of SSR. In the process of construction, we propose a task-oriented hybr…
【主题与分类】
主题标签:cs.CL。
【适用方向】
文本类数据可用于医学自然语言处理,如命名实体识别、信息抽取与文本分类。
【获取与许可】
源站页面:https://arxiv.org/abs/1905.01974v1
下载信息
注册下载
需要注册 Kaggle 账号并登录后下载,适合需要跟踪下载记录和使用 API 的用户。
暂未开放公开下载
无需注册即可直接获取公开样本或文档,适合快速预览和评估数据集质量。
免登录当前数据集主要来源为 Kaggle 公开托管,完整影像包建议通过原始链接或 Kaggle API 获取。
使用方式
数据集说明
任务导向型静默语音识别文本语料库 对应论文数据集(arXiv 预印本)。
数据获取指引
- 打开论文页面获取作者与项目信息:https://arxiv.org/abs/1905.01974v1
- 论文 Data Availability / Code Availability 章节标注了数据实际托管位置;
- 获取到实际数据链接后,按对应平台标准方式下载。
论文摘要:Abstract:Millions of people with severe speech disorders around the world may regain their communication capabilities through techniques of silent speech recognition (SSR). Using electroencephalography (EEG) as a biomarker for speech decoding has been popular for SSR. However, the lack of SSR text corpus has impeded the development of this technique. Here, we construct a novel task-oriented text corpus, which is utilized in the field of SSR. In the process of construction, we propose a task-oriented hybrid construction method based on natural language generation algorithm. The algorithm focuses on the strategy of data-to-text generation, and has two advantages including linguistic quality and high diversity. These two advantages use template-based method and deep neural networks respectively. In an SSR experiment with the generated text corpus, analysis results show that the performance of our hybrid construction method outperforms the pure method such as template-based natural language generation or neural natural language generation models.
需要用于商业化训练或医疗器械注册(NMPA/FDA)?
公开数据往往缺乏完整的病理回证与专家标注。千方医数集依托陕川双基地与超十家三甲医院直连,提供完全合规、去标识化、支持注册级质控的专病数据集交易服务。