抑郁症情绪数据集
一个包含6037个Reddit帖子的文本数据集,用于多标签分类检测抑郁症相关的8种情绪。
基本信息
资源简介
抑郁症情绪数据集
【数据集背景】
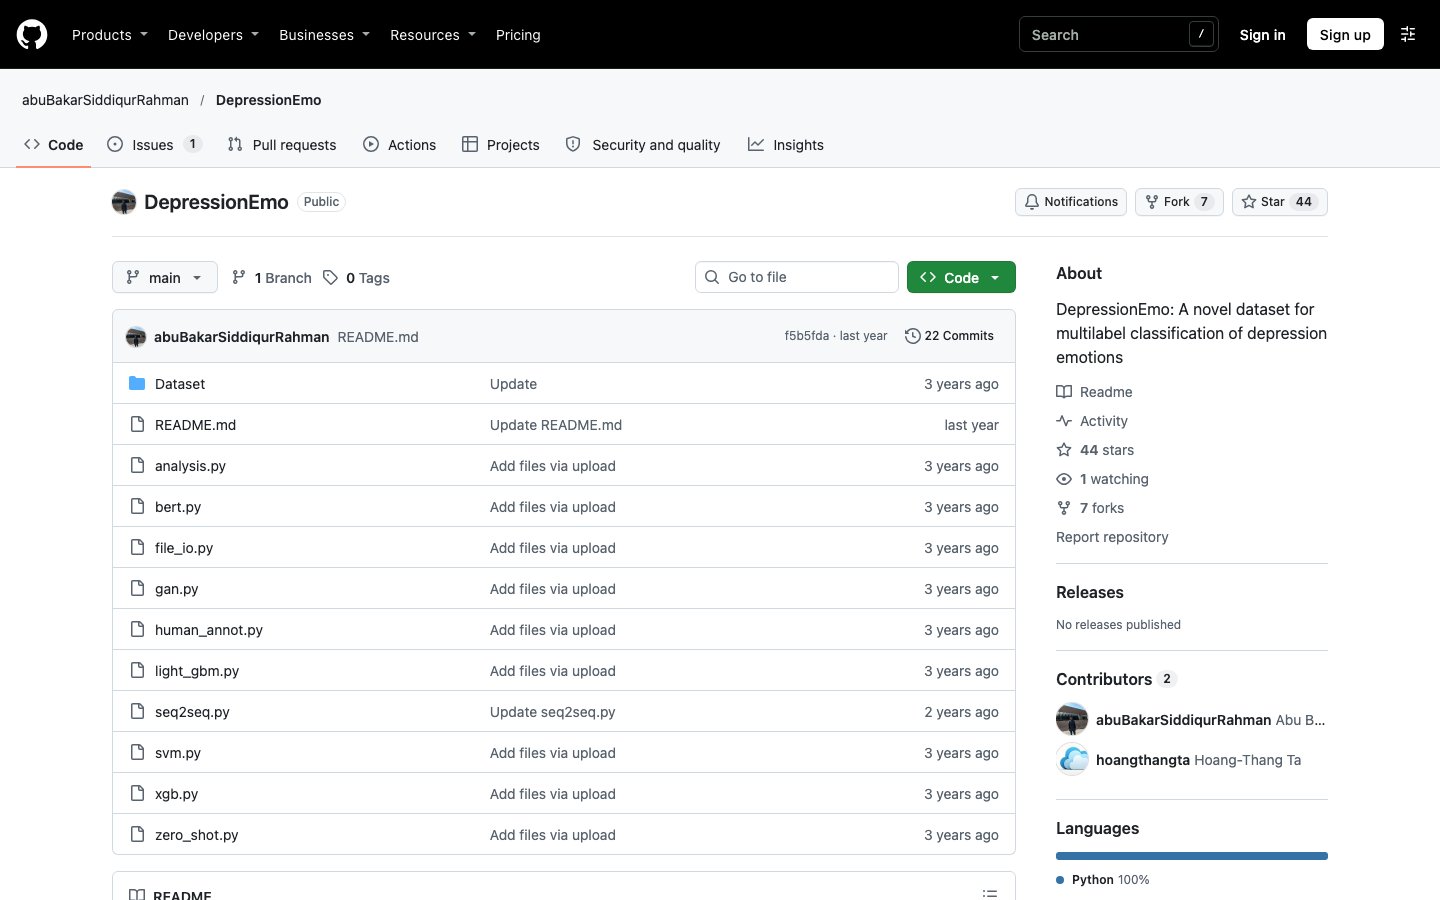
本数据集源站标题为《abuBakarSiddiqurRahman/DepressionEmo》。源站首次发布:2023-12-31。
【数据内容】
源站原始描述:DepressionEmo: A novel dataset for multilabel classification of depression emotions # DepressionEmo "DepressionEmo: A novel dataset for multilabel classification of depression emotions" If you use our dataset in your research paper, please make sure to cite the following paper: Rahman, A. B. S., Ta, H. T., Najjar, L., Azadmanesh, A., & Gönül, A. S. (2024). DepressionEmo: A novel dataset for multilabel classification of depression emotions. Journal of Affective Disorders. Use of the DepressionEmo…
【适用方向】
文本类数据可用于医学自然语言处理,如命名实体识别、信息抽取与文本分类。
【获取与许可】
源站页面:https://github.com/abuBakarSiddiqurRahman/DepressionEmo
【使用注意】
· 源站最后修改于 2025-11-09,引用时请注意版本时效。
下载信息
注册下载
需要注册 Kaggle 账号并登录后下载,适合需要跟踪下载记录和使用 API 的用户。
暂未开放公开下载
无需注册即可直接获取公开样本或文档,适合快速预览和评估数据集质量。
免登录当前数据集主要来源为 Kaggle 公开托管,完整影像包建议通过原始链接或 Kaggle API 获取。
使用方式
数据集获取
git clone https://github.com/abuBakarSiddiqurRahman/DepressionEmo.git

curl -L -o repo.zip https://github.com/abuBakarSiddiqurRahman/DepressionEmo/archive/refs/heads/main.zip
unzip repo.zip
源站 README 摘录(使用方式)
DepressionEmo
“DepressionEmo: A novel dataset for multilabel classification of depression emotions”
https://www.sciencedirect.com/science/article/abs/pii/S0165032724012278
https://arxiv.org/pdf/2401.04655.pdf
If you use our dataset in your research paper, please make sure to cite the following paper:
Rahman, A. B. S., Ta, H. T., Najjar, L., Azadmanesh, A., & Gönül, A. S. (2024). DepressionEmo: A novel dataset for multilabel classification of depression emotions. Journal of Affective Disorders. https://doi.org/10.1016/j.jad.2024.08.013
Use of the DepressionEmo dataset or a part of your whole dataset for developing any web application, mobile app, or commercial tool is strictly prohibited without prior written permission.
Please contact us at abu.rahman@hamptonu.edu before initiating any such use.
© 2024 Abu Bakar Siddiqur Rahman. All Rights Reserved.
Dataset
Subsets
The dataset is divided into 3 subsets:
- Training set
- Validation set
- Test set
An example data
Each example contains “id”, “title”, “post”, “text”, “upvotes”, “date”, “emotions”, and “label_id”. We use “text” (concatenate from “title” and “post”) for the depression detection.
{"id": "zq1lwl", "title": "goodbye.", "post": "I''m done. I have a bottle of jack danials and couple bottles of sleeping meds waiting for me when I get home. \n\nI''m excited to leave this place. There will be no regret, no loneliness, no sorrow, and no misery. I am looking forward to the peace of nonexistence.\n\nI love you all.", "text": "goodbye. ### I''m done. I have a bottle of jack danials and couple bottles of sleeping meds waiting for me when I get home. I''m excited to leave this place. There will be no regret, no loneliness, no sorrow, and no misery. I am looking forward to the peace of nonexistence. I love you all.", "upvotes": 102, "date": "2022-12-19 19:50:52", "emotions": ["emptiness", "hopelessness"], "label_id": 110000}
There are 8 depression emotions:
emotionevent-blocked= [''anger'', ''brain dysfunction (forget)'', ''emptiness'', ''hopelessness'', ''loneliness'', ''sadness'', ''suicide intent'', ''worthlessness'']
The “label_id” field is a number, whose each digit represents a state of with emotion (1) and without emotion (0). For example:
- [“emptiness”, “hopelessness”] -> 00110000 -> 110000
- [“anger”] -> 10000000
- [‘‘anger’’, ‘‘brain dysfunction (forget)’’, ‘‘emptiness’’, ‘‘hopelessness’’, ‘‘loneliness’’, ''sad
数据加载示例(表格/文本类)
import pandas as pd, glob, os

files = (glob.glob(os.path.join(path, "**", "*.csv"), recursive=True)
       + glob.glob(os.path.join(path, "**", "*.tsv"), recursive=True)
       + glob.glob(os.path.join(path, "**", "*.xlsx"), recursive=True))
print("数据文件:", files)
df = pd.read_csv(files[0])
print(df.shape); print(df.columns.tolist()); print(df.head(3))
需要用于商业化训练或医疗器械注册(NMPA/FDA)?
公开数据往往缺乏完整的病理回证与专家标注。千方医数集依托陕川双基地与超十家三甲医院直连,提供完全合规、去标识化、支持注册级质控的专病数据集交易服务。