甲状腺手术术前决策中ChatGPT-4o、Gemini Advanced与DeepSeek R1的比较评估
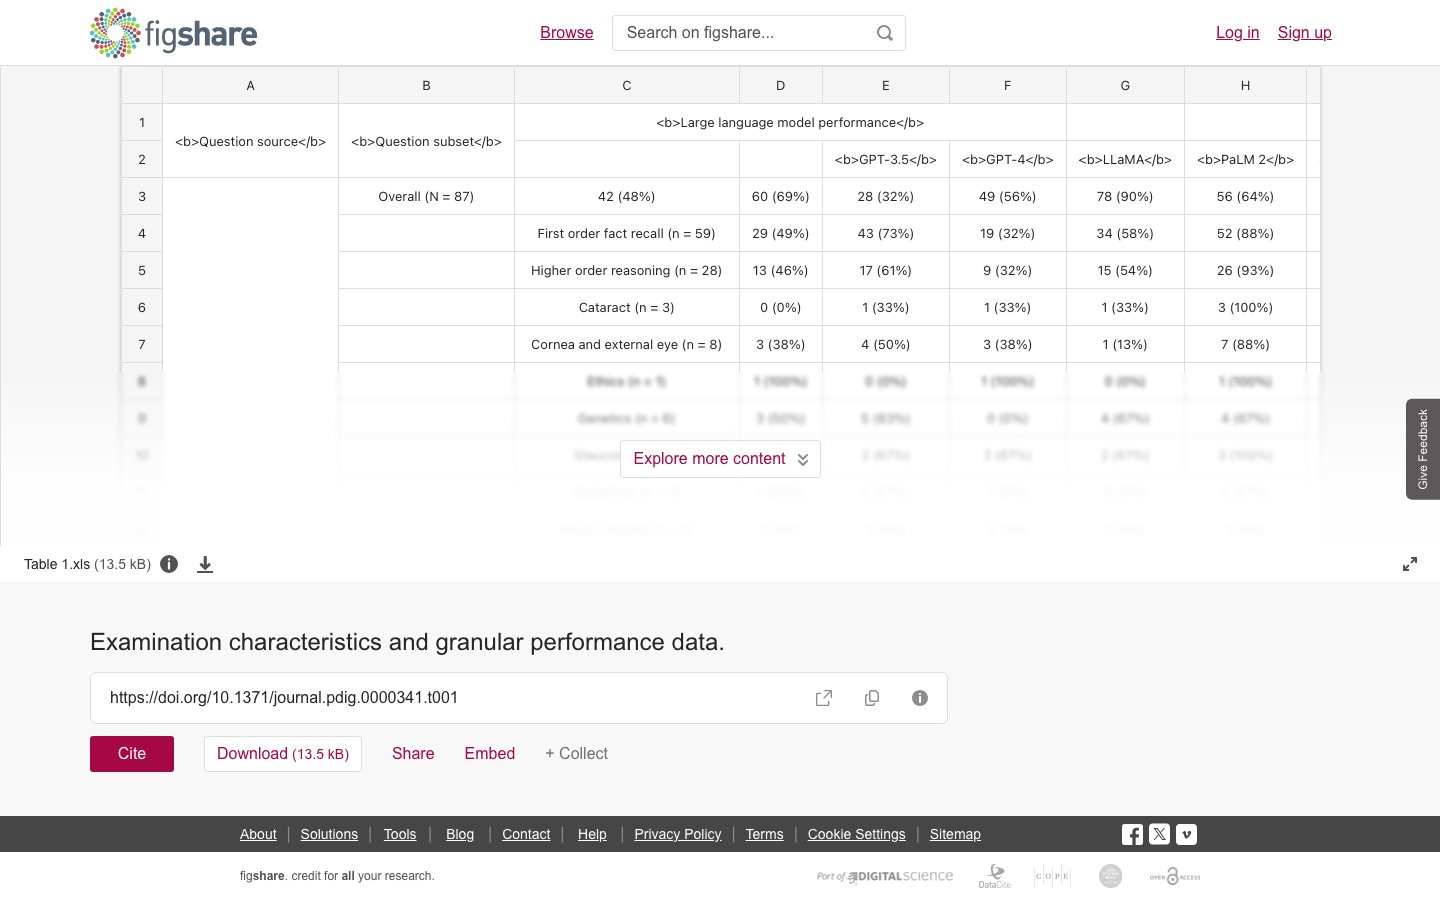
甲状腺手术术前决策中三种大语言模型(ChatGPT-4o、Gemini Advanced、DeepSeek R1)与外科专家共识的一致性比较表格数据。

基本信息
资源简介
甲状腺手术术前决策中ChatGPT-4o、Gemini Advanced与DeepSeek R1的比较评估
【一句话概览】
本数据集是 figshare 公开的结构化表格数据集,收录 1 个文件、合计 68.76 KB,主题涵盖 thyroid surgery、large language models、preoperative decision-making、clinical concordance、artificial intelligence,可用于统计建模、特征工程与队列分析,CC BY 4.0 许可开放获取。
【数据集背景】
本数据集源站标题为《Table 1_ChatGPT-4o, Gemini Advanced and DeepSeek R1 in preoperative decision-making for thyroid surgery: a comparative assessment with human surgeons.xlsx》。源站首次发布:2025-10-24。
【数据内容】
源站原始描述:The integration of large language models (LLMs) into surgical decision-making is an emerging field with potential clinical value. This study assessed the preoperative decision-making consistency of ChatGPT-4o, Gemini Advanced, and DeepSeek R1 in comparison with expert consensus, using clinical data from 123 patients undergoing thyroid surgery. Overall concordance rates were 47.97% for ChatGPT-4o, 24.39% for Gemini Advanced, and 56.10% for DeepSeek R1. In thyroidectomy extent decisions, all three…
【数据结构与技术规格】
文件数 1 个,合计 68.76 KB。Table 1_ChatGPT-4o, Gemini Advanced and DeepSeek R1 in preoperative decision-making for thyroid surgery: a comparative assessment with human surgeons.xlsx:application/vnd.openxmlformats-officedocument.spreadsheetml.sheet,68.76 KB。数据集 DOI:10.3389/fonc.2025.1590230.s001。
【主题与分类】
源站学科分类:Oncology and Carcinogenesis not elsewhere classified。主题标签:thyroid surgery、large language models、preoperative decision-making、clinical concordance、artificial intelligence。
【适用方向】
结构化表格数据可直接用于统计建模、特征工程与队列分析。
【获取与许可】
源站页面:https://frontiersin.figshare.com/articles/dataset/Table_1_ChatGPT-4o_Gemini_Advanced_and_DeepSeek_R1_in_preoperative_decision-making_for_thyroid_surgery_a_comparative_assessment_with_human_surgeons_xlsx/30435487
使用许可:CC BY 4.0(https://creativecommons.org/licenses/by/4.0/)。
规范引用:Zou, Long; Zhang, Peng; Jiang, Yu-qi; Wang, Xiao-wen; Yan, Xi-jing; Wu, Jie-zhong; et al. (2025). Table 1_ChatGPT-4o, Gemini Advanced and DeepSeek R1 in preoperative decision-making for thyroid surgery: a comparative assessment with human surgeons.xlsx. Frontiers. Dataset
下载信息
注册下载
需要注册 Kaggle 账号并登录后下载,适合需要跟踪下载记录和使用 API 的用户。
暂未开放公开下载
无需注册即可直接获取公开样本或文档,适合快速预览和评估数据集质量。
免登录有偿下载
公开数据集受托下载与技术交付服务。
提供高速下载与技术交付服务(收技术服务费,非数据销售)
暂未开放当前数据集主要来源为 Kaggle 公开托管,完整影像包建议通过原始链接或 Kaggle API 获取。
使用方式
数据集获取(Figshare)
- 源站标题:Table 1_ChatGPT-4o, Gemini Advanced and DeepSeek R1 in preoperative decision-making for thyroid surgery: a comparative assessment with human surgeons.xlsx
- DOI:10.3389/fonc.2025.1590230.s001
- 发布日期:2025-10-24
- 文件数:1 个
- 文件总体积:68.76 KB
- 源站页面:https://frontiersin.figshare.com/articles/dataset/Table_1_ChatGPT-4o_Gemini_Advanced_and_DeepSeek_R1_in_preoperative_decision-making_for_thyroid_surgery_a_comparative_assessment_with_human_surgeons_xlsx/30435487
命令行下载
curl -L -o "Table 1_ChatGPT-4o, Gemini Advanced and DeepSeek R1 in preoperative decision-making for thyroid surgery: a comparative assessment with human surgeons.xlsx" "https://ndownloader.figshare.com/files/59004292"
文件清单
Table 1_ChatGPT-4o, Gemini Advanced and DeepSeek R1 in preoperative decision-making for thyroid surgery: a comparative assessment with human surgeons.xlsx(68.76 KB)
文件总体积 68.76 KB(源站 API 实测)。
数据说明
The integration of large language models (LLMs) into surgical decision-making is an emerging field with potential clinical value. This study assessed the preoperative decision-making consistency of ChatGPT-4o, Gemini Advanced, and DeepSeek R1 in comparison with expert consensus, using clinical data from 123 patients undergoing thyroid surgery. Overall concordance rates were 47.97% for ChatGPT-4o, 24.39% for Gemini Advanced, and 56.10% for DeepSeek R1. In thyroidectomy extent decisions, all three models showed moderate consistency with the surgical team, with agreement rates of 61.79% (κ=0.484) for ChatGPT-4o, 67.48% (κ=0.548) for Gemini, and 67.48% (κ=0.535) for DeepSeek R1 (all p < 0.001). However, significant divergence was observed in lymph node dissection planning: ChatGPT-4o achieved a high concordance rate of 69.11% (κ=0.616), DeepSeek R1 showed the highest at 79.67% (κ=0.741), while Gemini’s performance was relatively poor at 34.96% (κ=0.188). Though our findings demonstrate that ChatGPT-4o and DeepSeek R1 exhibit substantial agreement with experienced surgeons in preoperative planning, overall performance still leaves room for improvement. Nevertheless, model-specific variability—particularly in oncologic decision-making—highlights the need for refinement and robust clinical validation before widespread clinical adoption.
许可
CC BY 4.0
引用
学术使用请引用 DOI 10.3389/fonc.2025.1590230.s001(source: https://frontiersin.figshare.com/articles/dataset/Table_1_ChatGPT-4o_Gemini_Advanced_and_DeepSeek_R1_in_preoperative_decision-making_for_thyroid_surgery_a_comparative_assessment_with_human_surgeons_xlsx/30435487)。
数据缺失?
依托陕西、四川两大基地,我们与超过十家三甲医院建立直接合作关系,覆盖合规授权、采集治理、专业标注、数据交付的全流程,为AI医疗团队提供即拿即用的高质量临床数据。
⚡️ 需要数据支持或标注服务?立即联系我们获取专业方案。