PIMA数据集
包含PIMA Indian等多个子集的糖尿病预测表格数据集,用于机器学习算法对比研究。

基本信息
资源简介
PIMA数据集
【数据集背景】
本数据集源站标题为《PIMA dataset.》。源站首次发布:2025-10-21。
【数据内容】
源站原始描述:Diabetes mellitus presents a significant global health challenge, particularly in regions like Pakistan, India, and Bangladesh. Machine learning (ML) techniques offer promising solutions for diabetes prediction, surpassing traditional methods in reliability and efficiency. This research conducts a comparative analysis of ML algorithms including Random Forest (RF), Decision Tree (DT), Support Vector Machine (SVM), K-nearest neighbors (KNN), Gradient Boosting (GB), RaSK_GraDe (Proposed Voting), an…
【数据结构与技术规格】
文件数 1 个,合计 5.63 KB。Table 8.xls:application/vnd.ms-excel,5.63 KB。数据集 DOI:10.1371/journal.pone.0327661.t008。
【主题与分类】
源站学科分类:Biotechnology、Chemical Sciences not elsewhere classified、Biological Sciences not elsewhere classified、Information Systems not elsewhere classified、Mathematical Sciences not elsewhere classified、Science Policy。主题标签:svm ), k、surpassing traditional methods、regions like pakistan、performed using datasets、gb ), rask_grade、achieving notable accuracies、55 %, respectively、proposed voting ),、proposed stacking ).、frankfurt hospitals diabetes。
【适用方向】
结构化表格数据可直接用于统计建模、特征工程与队列分析。
【获取与许可】
源站页面:https://plos.figshare.com/articles/dataset/PIMA_dataset_/30410402
使用许可:CC BY 4.0(https://creativecommons.org/licenses/by/4.0/)。
规范引用:Noman, Muhammad; Hanif, Maria; Hameed, Abdul; Babar, Muhammad; Qureshi, Basit (2025). PIMA dataset.. PLOS ONE. Dataset
下载信息
注册下载
需要注册 Kaggle 账号并登录后下载,适合需要跟踪下载记录和使用 API 的用户。
暂未开放公开下载
无需注册即可直接获取公开样本或文档,适合快速预览和评估数据集质量。
免登录当前数据集主要来源为 Kaggle 公开托管,完整影像包建议通过原始链接或 Kaggle API 获取。
使用方式
数据集获取(Figshare)
- 源站标题:PIMA dataset.
- DOI:10.1371/journal.pone.0327661.t008
- 发布日期:2025-10-21
- 文件数:1 个
- 文件总体积:5.63 KB
- 源站页面:https://plos.figshare.com/articles/dataset/PIMA_dataset_/30410402
命令行下载
curl -L -o "Table 8.xls" "https://ndownloader.figshare.com/files/58930757"
文件清单
Table 8.xls(5.63 KB)
文件总体积 5.63 KB(源站 API 实测)。
数据说明
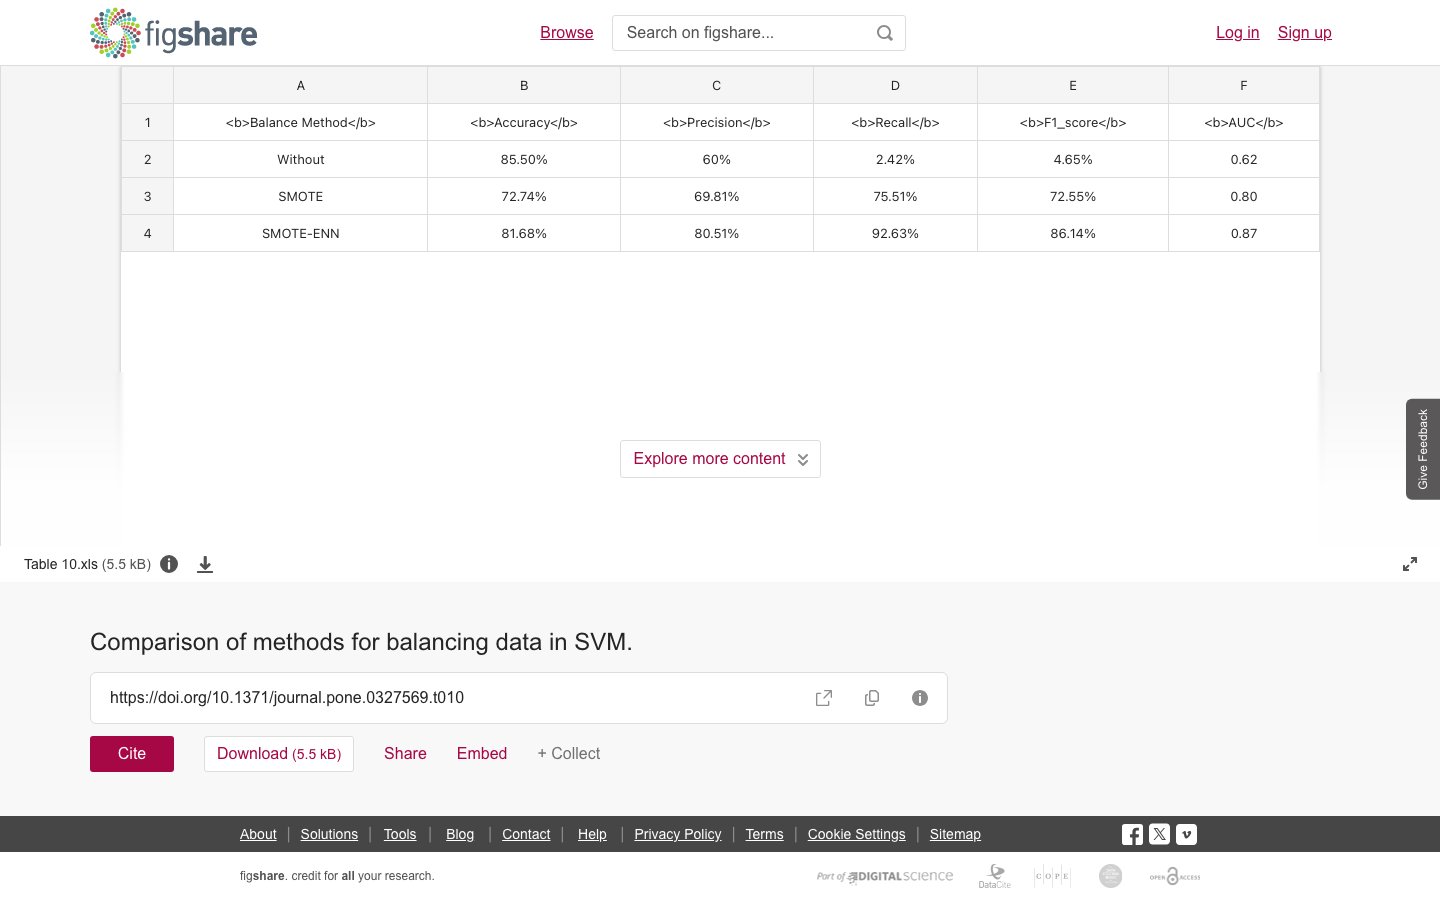
Diabetes mellitus presents a significant global health challenge, particularly in regions like Pakistan, India, and Bangladesh. Machine learning (ML) techniques offer promising solutions for diabetes prediction, surpassing traditional methods in reliability and efficiency. This research conducts a comparative analysis of ML algorithms including Random Forest (RF), Decision Tree (DT), Support Vector Machine (SVM), K-nearest neighbors (KNN), Gradient Boosting (GB), RaSK_GraDe (Proposed Voting), and RaSK_GraDeL (Proposed Stacking). Evaluation is performed using datasets, such as PIMA Indian, Frankfurt Hospitals Diabetes, RTML with Insulin, and the proposed Diabetes Health Tracer (DHT) dataset comprising 2877 observations with nine features. Data pre-processing techniques address missing values, outliers, normalization, and class balancing (SMOTE), enhancing model robustness. Hyperparameter tuning via cross-validation and Random Search optimizes model performance. Additionally, ensemble methods—Voting Classifier (RaSK GraDe) and Stacking Model (RaSK GraDeL with Logistic Regression) are applied, achieving notable accuracies of 98.03% and 98.55%, respectively, on the DHT dataset. The study underscores ML’s potential in diabetes prediction, advocating for personalized treatment and healthcare management advancements.
许可
CC BY 4.0
引用
学术使用请引用 DOI 10.1371/journal.pone.0327661.t008(source: https://plos.figshare.com/articles/dataset/PIMA_dataset_/30410402)。
需要用于商业化训练或医疗器械注册(NMPA/FDA)?
公开数据往往缺乏完整的病理回证与专家标注。千方医数集依托陕川双基地与超十家三甲医院直连,提供完全合规、去标识化、支持注册级质控的专病数据集交易服务。