MDD-5k
中文精神障碍诊断对话数据集,基于1000个真实患者案例生成5000个高质量诊断对话,用于辅助诊断聊天机器人和精神障碍分类。
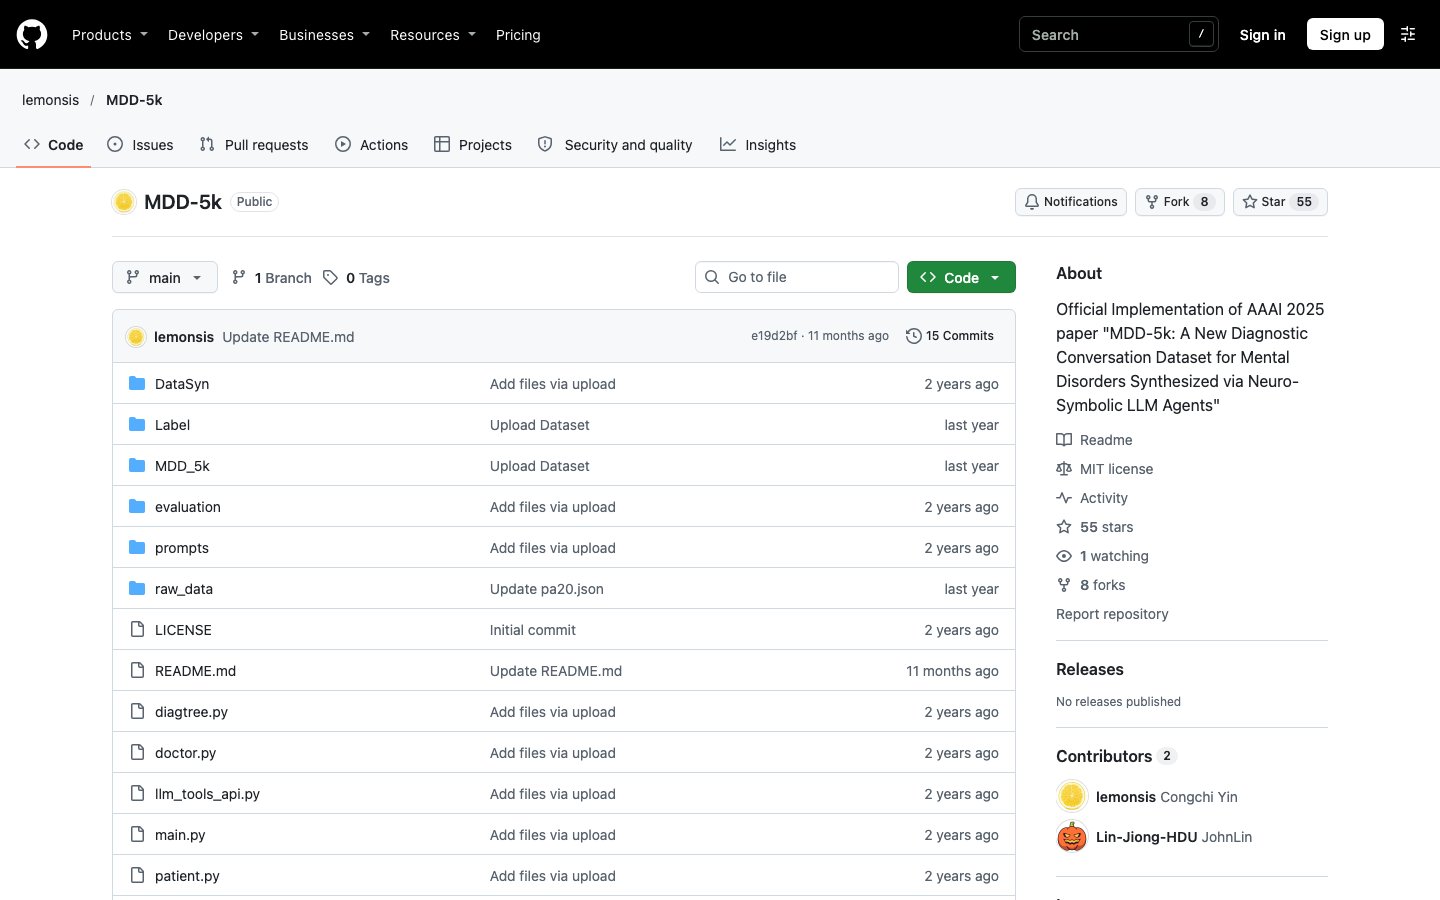
基本信息
资源简介
MDD-5k
【数据集背景】
本数据集源站标题为《lemonsis/MDD-5k》。源站首次发布:2024-08-18。
【数据内容】
源站原始描述:Official Implementation of AAAI 2025 paper "MDD-5k: A New Diagnostic Conversation Dataset for Mental Disorders Synthesized via Neuro-Symbolic LLM Agents" # MDD-5k Official Implementation of AAAI 2025 paper "MDD-5k: A New Diagnostic Conversation Dataset for Mental Disorders Synthesized via Neuro-Symbolic LLM Agents" ## Dataset Overview MDD-5k is build upon 926 unique patient files, and each patient file is used to synthesize five diagnostic conversations, resulting in a total of 4630 conversation…
【适用方向】
文本类数据可用于医学自然语言处理,如命名实体识别、信息抽取与文本分类。
【获取与许可】
源站页面:https://github.com/lemonsis/MDD-5k
使用许可:MIT。
【使用注意】
· 源站最后修改于 2025-12-08,引用时请注意版本时效。
下载信息
注册下载
需要注册 Kaggle 账号并登录后下载,适合需要跟踪下载记录和使用 API 的用户。
暂未开放公开下载
无需注册即可直接获取公开样本或文档,适合快速预览和评估数据集质量。
免登录当前数据集主要来源为 Kaggle 公开托管,完整影像包建议通过原始链接或 Kaggle API 获取。
使用方式
数据集获取
git clone https://github.com/lemonsis/MDD-5k.git

curl -L -o repo.zip https://github.com/lemonsis/MDD-5k/archive/refs/heads/main.zip
unzip repo.zip
源站 README 摘录(使用方式)
MDD-5k
Official Implementation of AAAI 2025 paper “MDD-5k: A New Diagnostic Conversation Dataset for Mental Disorders Synthesized via Neuro-Symbolic LLM Agents”
Dataset Overview
MDD-5k is build upon 926 unique patient files, and each patient file is used to synthesize five diagnostic conversations, resulting in a total of 4630 conversations.
The synthetic conversations and corresponding lables can be found in ./MDD_5k and ./Label. Each json file in ./MDD_5k contains five conversations and all the five conversation is generated based on the same patient file.
Preprocessing Steps
Run python patient_template_gen.py to get statistics of MDD-5k dataset and generate fictitious patient experiences
Synthesize Diagnostic Conversation
Current code only supports using deployed model for generation. You can either access state-of-the-art GPT model through OpenAI API keys, or deploying local models with vLLM. For the former way, enter your OpenAI key in line 37 of llm_tools_api.py. For the latter way, enter the key and server host in line 44 and 45 of llm_tools_api.py. For OpenAI LLMs, we found the performance of gpt-4o is the best.
Then run python main.py to start synthesizing data.
Example
One real patient case is shown in ./raw_data/pa20.json. Five fictitious patient experiences generated with this patient case are shown in ./prompts/background_story/patient_1. The synthesized diagnostic conversations are in ./DataSyn/patient1.json.
数据加载示例(表格/文本类)
import pandas as pd, glob, os

files = (glob.glob(os.path.join(path, "**", "*.csv"), recursive=True)
       + glob.glob(os.path.join(path, "**", "*.tsv"), recursive=True)
       + glob.glob(os.path.join(path, "**", "*.xlsx"), recursive=True))
print("数据文件:", files)
df = pd.read_csv(files[0])
print(df.shape); print(df.columns.tolist()); print(df.head(3))
需要用于商业化训练或医疗器械注册(NMPA/FDA)?
公开数据往往缺乏完整的病理回证与专家标注。千方医数集依托陕川双基地与超十家三甲医院直连,提供完全合规、去标识化、支持注册级质控的专病数据集交易服务。